Contents
An enterprise SEO audit is a four to six week review of how a large website is crawled, rendered, indexed and ranked, and how it appears on AI search. It ends in a prioritised list of fixes tied to revenue. This is how I run mine: what I check, in what order, the numbers I work with, and what I leave out. Everything here comes from my own audits over 14+ years.
The short version
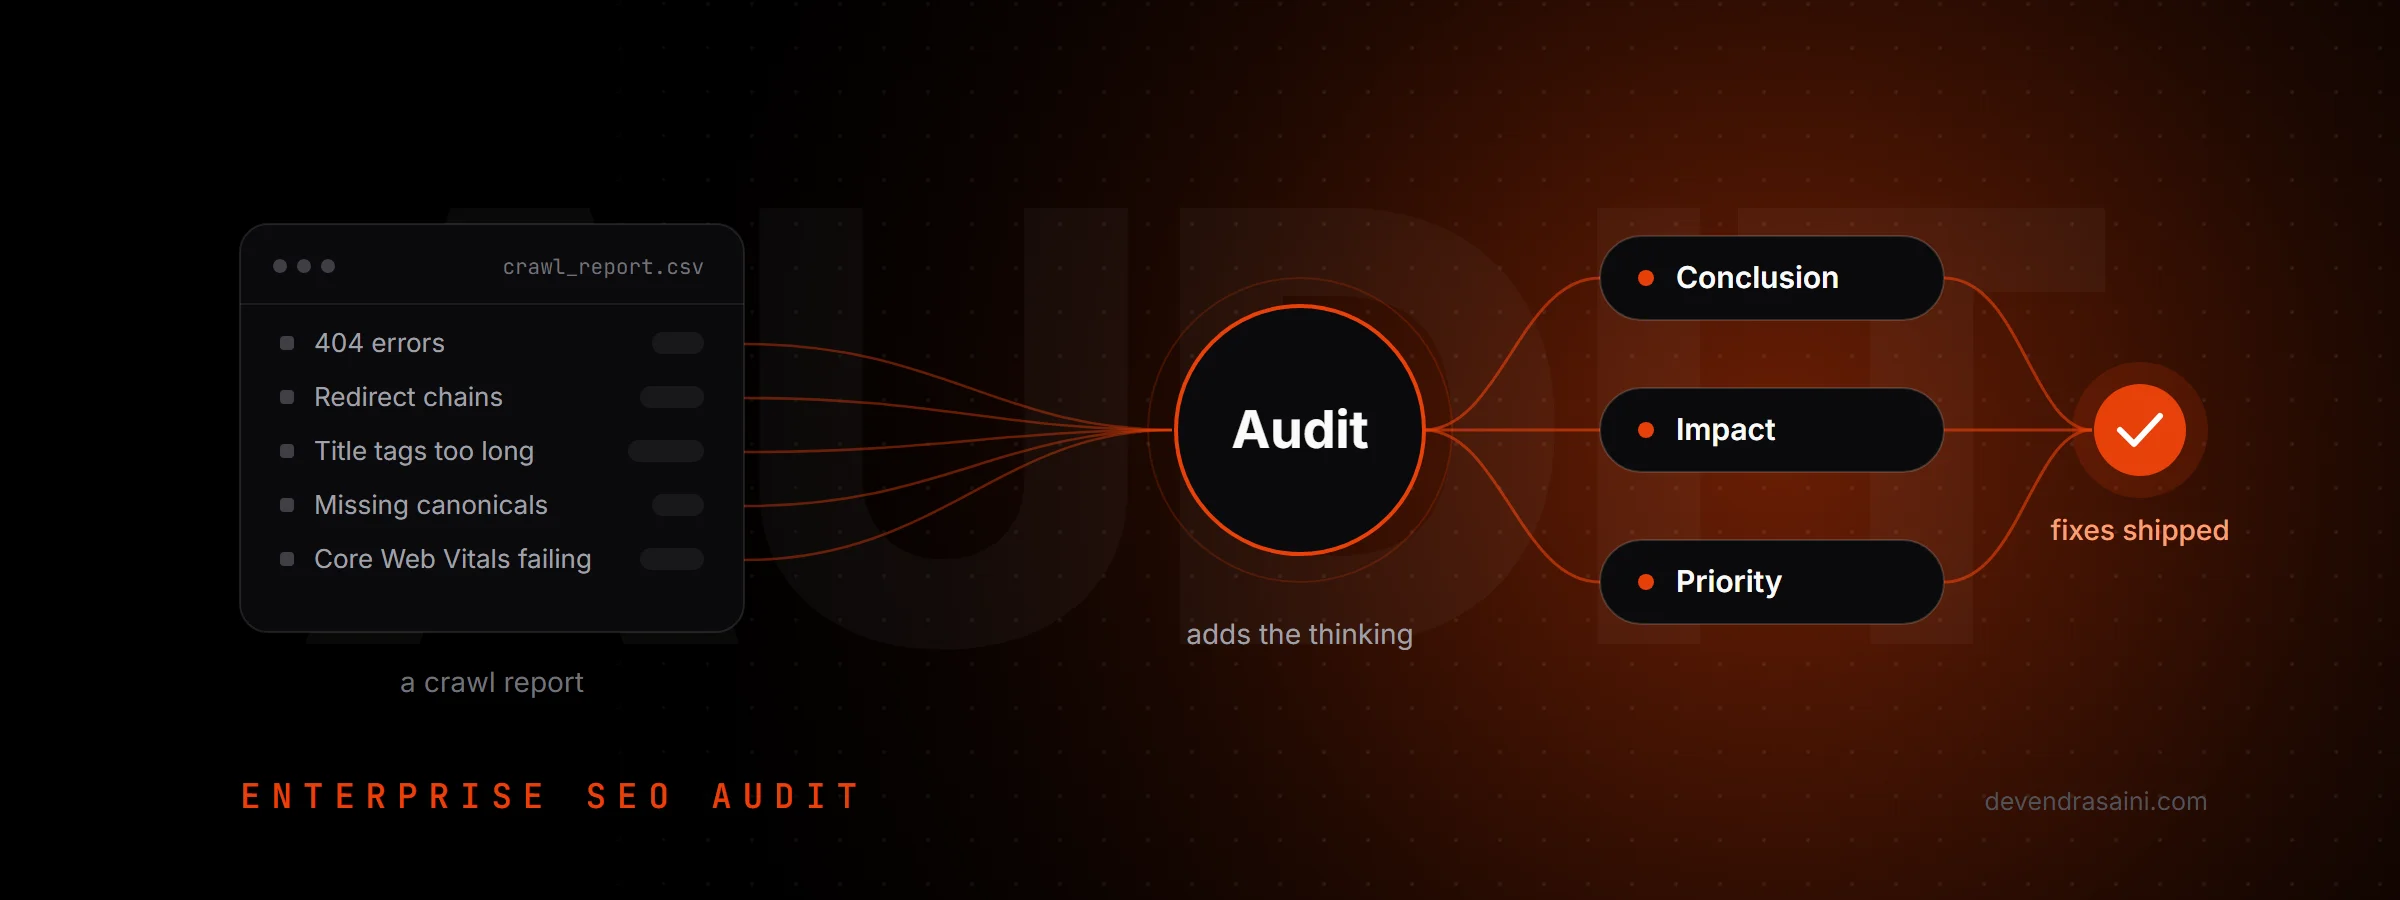
- A crawl report is not an audit. An audit gives the conclusion of every finding and shows how fixing it helps the brand grow.
- You do not need to audit every page. I audit template types and folder segments.
- Four weeks is my fastest time for an enterprise audit, even with AI. Anything faster misses something.
- Rendering comes first. In about 99 of 100 large audits, I find content that is not rendered properly.
- For decayed content, removal matters more than re-optimisation.
- Check AI crawlers in robots.txt, the CDN and the firewall. Treat llms.txt as hygiene, not as a visibility lever.
- Fix the lowest-effort, highest-impact items first. If nothing gets implemented, no results will come.
A crawl report is not an audit
I review many audits delivered by agencies. Most are filled with generic suggestions, built on the direct output of a tool: a Semrush, Ahrefs or Screaming Frog export.
The tool output is not bad. But presenting a crawl report as an audit is a scam. An audit has to state the conclusion of each finding and show exactly how fixing it helps the brand grow. If a client is charged thousands of dollars and receives no added value, it is a scam.
Most of these audits contain no execution. They list 404s, redirect counts, redirect chains, HSTS policies, title tags over the character limit and failing Core Web Vitals. All of those are fancy suggestions. Some are useful, but the expert has added nothing of their own.
A brand can buy a tool subscription and get the same report. So what is the consultant for? Most of these audits do not contain even 10% of what we deliver. A crawl report is not an audit. It is a crawl report.
Many also sell whatever is trending, such as llms.txt, or tell the brand it is "missing" an item that most sites do not have. I have seen audits filled with suggestions whose only purpose is to prove that something was found. They have no merit. That is the difference between my audit and the rest.
| Crawl report | Audit | |
|---|---|---|
| What you get | A list of errors from a tool | The conclusion of every finding |
| Impact | Not stated | Tied to business leads and revenue |
| Order | Four or five suggestions at random | Effort, impact and priority for every item |
| Benchmarking | None, or the wrong competitors | The right competitors and the search demand of the category |
| Execution | "We need to fix this" | An executable instruction for every item, then a PRD or TRD once it is prioritised |
How to do an enterprise SEO audit: my four-week process
The time depends on the size of the website and the business. The bigger the site, the longer the audit. A full enterprise audit from scratch used to take me four to six weeks. With my AI workflows it now takes four, and that is the fastest I can do it properly.
Two to three weeks go into the data: crawl reports, Search Console, queries and segmentation, the content audit, the site's history, links and structure. Then comes a competitive analysis and a study of the search ecosystem in the category, to learn what is working there.
I then need at least a week to turn the findings into a story. The deck must explain three things clearly: what to execute, what needs attention first, and the red flags.
Anything faster will always miss out on something. In spite of using a lot of AI, we cannot actually trust AI.
I review my workflows and double-check the output, because the document we share is the final product.
Segment by template and folder, not by page
You do not need to audit every page. A large site is built from templates, so I audit template types and segments. That shows how the linking and crawl structure work.
I start with Ahrefs. Its Site structure report shows how the folders and sub-folders are organised. For sites above 100,000 pages, I segment further with Claude and a Screaming Frog MCP setup. This shows which folders are lagging, which earn the most traffic, and which were hit in the last update.
For reference. Screaming Frog added an official MCP in SEO Spider version 24.0 in May 2026. Ahrefs and Semrush document their own MCP servers.
Enterprise SEO audit checklist: the numbers I work with
These are the checks in my audit, with the number I use for each. They are my own numbers from my own audits, not industry statistics.
| Check | What I look for | My number |
|---|---|---|
| JavaScript rendering | Content in the browser that is missing from the server-side copy | An issue in about 99 of 100 large audits |
| Click depth | How many clicks it takes to reach any page | 3 to 4 clicks at most |
| Crawl frequency | URLs Googlebot has stopped visiting | Not crawled for 60 to 90 days: very likely no value |
| Googlebot's share | Google versus AI crawlers in the server logs | About 40% of search crawl hits now |
| Backlinks | Built links that pass no equity | 50 to 60% for many brands |
| Content pruning | Blog posts written without real expertise | Sometimes 80 to 90% has to go |
| Page monitoring | On-page parameters tracked on every page | 28 to 30 |
| Implementation | Recommendations shipped per quarter | 10 to 30% in large enterprises, 80 to 90% in fast startups |
| Timeline | A full enterprise audit | 4 weeks with AI, 4 to 6 without |
The enterprise technical SEO audit
Content that Google cannot render is the lowest-effort, highest-impact fix I know. So the technical audit starts there.
JavaScript rendering: the three-way check
JavaScript rendering is a critical area. In about 99 of 100 large audits, I find some content that is not rendered properly.
Large sites load much of their content through JavaScript, using frameworks such as React to keep pages fast. That is fine. The risk is that JavaScript changes the content after the page loads. If that content is not in the server-side copy, a crawler that does not run JavaScript will never see it. It is visible to the user and missing for the crawler, which is lethal.
I run a three-way check, and my SSR Inspector Chrome extension does the same.
Check mobile and desktop separately. Rendering differs between the two, so the desktop copy can look fine while the mobile copy is broken. Most people skip this.
Google has improved its crawling and now handles most JavaScript frameworks well. Other AI crawlers are still catching up.
What the documentation says. Google renders pages with a headless Chromium and indexes the rendered HTML, and it indexes the mobile version of a page. In the study Vercel and MERJ published in December 2024, none of the OpenAI, Anthropic or Perplexity crawlers they tracked ran JavaScript.
Boni Satani recently featured SSR Inspector at SaaS SEO Alliance 2.0 in Delhi, in September 2026.
The migration that lost 90% of its traffic in two weeks
The worst migrations are the ones done without the SEO and technical SEO teams. That is an invitation to a massive loss of organic traffic.
I was auditing DailyObjects, a popular Indian ecommerce site, when it moved from Magento, a PHP-based platform, to an Angular JavaScript framework. At that time Angular did not support server-side rendering. The team completed the migration, including the URL redirects. But Google could not render the pages, and the site lost almost 90% of its organic traffic within two weeks.
Our audit identified the framework as the cause, and we fixed it with Prerender.io. Recovery took three months, because Google had to crawl the site again. The site then regained almost all of its earlier traffic, and grew to about twice that level over the next six months.
For accuracy. This was the first-generation AngularJS. Angular has supported server-side rendering for years now, and DailyObjects today serves server-rendered pages. Prerendering for crawlers is what Google calls dynamic rendering, which it now treats as a workaround, not a long-term solution.
Site migration SEO checklist
There are three types of migration: a new URL structure on the same domain, a new theme or design on the same domain, and a move to a new domain with new URLs. All three need serious testing and monitoring. This is the checklist I work from.
Before the move
- Bring in the SEO and technical SEO teams before any work starts.
- Name the type of move: new URLs, a new design, or a new domain.
- Run the three-way rendering check on the new build, on mobile and desktop.
- Map every current URL to its new URL.
- Vet the release on staging. SEO, content and brand teams sign off.
On launch day
- Set permanent, server-side redirects from every old URL to its new one.
- For a domain move, put the domain-level redirection in place.
- For a domain move, declare it in Search Console with the Change of Address tool.
After the move
- Watch the server logs in real time for a spike in 404s.
- Monitor traffic on both the old and the new URLs.
- Re-check that the redirects are still intact, weeks and months later.
In every audit
- Has this site migrated in the past, and did traffic fall afterwards?
- How was that migration carried out?
What the documentation says. The URL mapping, server-side redirect and monitoring steps follow Google's site move guide, which says a small or medium site takes a few weeks to move and a large site longer. The Change of Address tool applies only when the domain or subdomain changes.
Index bloat: de-index first, then block
You will always find bloat. Some sections were never meant to be indexed. They exist for technical reasons and consume crawl budget: tag pages, category pages, filter pages, parameterised URLs and pagination. At scale, one bad rule in the logic can index thousands or lakhs (hundreds of thousands) of URLs: duplicates, non-canonical versions and self-canonicalised copies. Even staging URLs get indexed.
Index bloat is a serious issue. It causes cannibalisation. In my experience it also exposes a site to softer algorithmic and core update hits, when unregulated sections make the index far larger than the part of the site that ranks. I find it with search operators, Search Console's index reports and crawl patterns. It is a low-effort, high-impact fix.
What the documentation says. Google's noindex rule only works if the page is not blocked by robots.txt, which is why the order matters. Google itself does not use the term index bloat: John Mueller said in the June 2023 SEO office hours that he is not aware of any such concept at Google. It is my working term, and the link to update hits is what I have seen in audits.
Server logs: what Google and the AI crawlers actually do
Server logs show your whole crawl ecosystem: which user agent visited, how, and which sections. They also work in real time. A 404 spike can trigger an alert at once, while crawl tools and search engine reports run a couple of days behind.
In current log data from two large sites I work with, Googlebot is always among the top three search crawlers. Google now accounts for about 40% of search crawl hits, because OpenAI and other AI crawlers have arrived. In some cases they crawl almost as much as Google. OpenAI does not crawl whole sites, though. It prefers certain pages and recrawls those more often.
Crawl data also shows how much Google trusts a URL. If Google keeps crawling a URL but leaves it in "Crawled - currently not indexed", its crawl frequency will very likely fall. If a URL has not been crawled for 60 to 90 days, it very likely adds no value. It may be part of the index bloat, or a sign of content decay.
For reference. The 60 to 90 days is my own line. A separate study by Indexing Insight of 1.4 million pages found that pages not crawled in the last 130 days had a 99% chance of not being indexed. A user agent in the logs can be faked, so confirm AI bot hits against the IP ranges the vendors publish.
Internal linking: audit the logic
On a large site, internal linking is handled programmatically, so I audit the logic. Are there pages that are not being crawled? Are they orphaned or well linked? Every page should be reachable within three to four clicks. Is the pagination correct? Does the footer link logic work?
The bigger risk is over-optimisation. In the last couple of spam updates, I have seen internal linking that is almost spam: too many links from one page, keyword-heavy anchors, and blog posts linking to money pages they have nothing to do with. People ignore these small details, and that is where they get penalised heavily.
What the documentation says. Google's link spam policy does not name internal links. Its link best practices say to write anchor text naturally and not to cram in keywords. The spam risk is my observation from audits.
Core Web Vitals: a hygiene item
Core Web Vitals are one of the most abused metrics in audits. Snake oil agencies add them to every list of recommendations. The mistake is tying them heavily to rankings.
If your pages take eight or ten seconds to load, fix it. My working target is two to three seconds. A slow page costs you rankings, revenue and users. Everyone likes fast pages.
If your pages are already fast, the last half second, or 200 to 300 milliseconds, takes a huge engineering effort to find. An SEO should know where this recommendation matters, and where it should not be raised at all. Speed is a hygiene item, and it belongs to product, UI/UX and engineering as much as to SEO.
What the documentation says. The official good thresholds are 2.5 seconds for LCP, 200 milliseconds for INP and 0.1 for CLS, measured at the 75th percentile of page loads. Google says Core Web Vitals are used by its ranking systems, and in the same answer that good scores do not guarantee top rankings.
International structure
How you expand depends on your business, your technical capability and your budget. First understand how customers search. Should one page rank in several countries, or should each page rank in one?
| Structure | When it fits | What it needs |
|---|---|---|
| Country domains (ccTLD) | The audience and the product line differ in every country | Budget to acquire every local domain, and engineering to keep each one distinct |
| Sub-directories | One domain expanded into local sections, such as /en-us/ | A well-balanced international SEO setup, because every section shares the authority of one domain |
| One global site | Everything is in one language and each page has a single version | Pages built to serve several geographies |
Do not publish direct translations without review by real translators, or by people who understand your customer. I have seen many brands lose pages, rankings or indexing in updates because their content was scaled purely with AI.
What the documentation says. Google lists country domains, subdomains and subdirectories and names no winner. The one global site is my own third option. The hreflang value for the United Kingdom is en-GB, not en-UK.
The content audit
Programmatic pages: everything comes down to value
I judge a programmatic template by the unique value it provides. Does the business really offer the services, areas or products the template claims? Pages scaled only for SEO fall under scaled content abuse. Everything comes down to value.
Done wrong, programmatic pages risk a manual action or an algorithmic penalty. Handle them with extreme caution. They are a double-edged sword.
My best result came from fixing cannibalisation on a programmatic setup. A luggage storage marketplace had city pages and area pages that looked alike. A search for "luggage storage near Penn Station" would return a different area page, or the city page. Its primary keywords sat at the bottom of page one, or on page two.
We changed the page structure and the content. We made each page unique, removed duplicate keywords across pages, and rewrote the content that was too similar, so that Google could treat every page and area as distinct. By 2020 many of those keywords ranked in the top three, and the brand stayed on page one for most of its main terms until 2022.
What the documentation says. Google defines scaled content abuse as generating many pages mainly to manipulate rankings, however the content is created. So the test is value, not the tool.
Entities: deliver the concept as content executables
Entities are the building blocks of knowledge graphs. They are how an algorithm understands that two things are related. I start with one question: which category is this business most closely tied to? That is the entity. Then I check whether the related entities are covered on the site, and whether a topic needs its own page or belongs on an existing one without causing cannibalisation.
I do not go deep into entities in an audit. The topic has gone overboard since AI, and many professionals use the term to sound clever instead of making it executable. My aim is to turn the concept into content executables: a content gap analysis the team can act on.
Content decay: removal matters more than re-optimisation
Content decay used to be simple. Find the outdated pages that lost impressions, re-optimise them, and the traffic came back.
That changed in the last year. Many pages that Google dropped were not decayed at all. The drop can mean the page does not belong on your site, or that you are not the right source for that topic. So I segment the drops: soft, hard, and pages that have fallen out of their query set entirely. This segmentation is extremely important.
| What the data shows | What I recommend |
|---|---|
| A soft drop, or stale numbers and facts | Re-optimise |
| A hard drop, such as top three to outside the top 100, on a topic you are not the right expert for | Remove |
| Google has stopped ranking the page for its query set | Remove |
A large body of content that keeps dropping is a sign that Google does not treat you as an authority on those topics. Researching keywords and writing loosely around your broader category, the old "SEO content writer" method, no longer works.
Pruning: less is more
I have seen many brands grow after removing content rather than publishing more. Less is more works for SEO. You should not write about everything. I sometimes ask brands to remove 80 to 90% of their blog posts, because the quality is that poor.
I once told a brand that its whole blog was close to a penalty. Much of the content had no legitimacy. There was no real expert behind it, only a team of SEO content writers and interns. I asked them to remove almost 2,000 of 2,400 articles. The brand did not listen. It re-optimised with the same approach.
Six months later I learnt that the blog had received a manual action and was completely de-indexed. This is what is happening across the industry now.
My rule is strict. If content is merely average, remove it or rewrite it completely. If the topic is outside your core business and you have no real expertise in it, remove it.
What the documentation says. A manual action can cover part of a site, for example everything under one directory. Google issues one where a human reviewer finds pages that break its spam policies. Falling rankings by themselves do not trigger one.
Links and competitors
Backlinks have lost their charm
Backlinks are still a ranking factor, but they have lost their charm over the last five to six years. They are one of the most abused ranking signals. The industry is full of people selling guest posts, PBN links and expired domains, and most of the link building that used to work no longer does.
For many brands, 50 to 60% of the links built in the last five years pass no equity. You can remove them and see no change in rankings. If you are part of a link scheme, be careful. You are one manual action away.
Links still matter when they come naturally from PR. In my view, AI search draws much of its retrieval and training from brand mentions and links on other websites. So spend the link budget on content that earns links: people-first content, proprietary research, statistics and digital PR.
What the documentation says. Google's ranking guide confirms that link analysis is still part of its core ranking systems. Its link spam policy covers buying or selling links, including paid posts. Its disavow guidance is narrow: use the tool only when a considerable number of spammy links have caused a manual action, or are likely to cause one.
Competitor benchmarking: get inspired, do not copy
Competitive benchmarking is an extremely important part of the audit. Know who you compete with, how long they have been in the space, their authority, their page structure and their share of the market.
But do not copy their structure exactly. This is where most brands go wrong. You never know whether a competitor's strategy is spam, or how long it will keep working.
Competitor benchmarking is crucial. But copying a competitor exactly is a lethal move.
The AI search layer
Tracking visibility is one part of the audit. Finding the technical and crawling gaps is another. On AI search you need both.
AI crawlers: robots.txt, the CDN and the firewall
Many brands block GPTBot, ClaudeBot, PerplexityBot and other AI crawlers. So I check how AI crawlers reach the site. First, confirm in robots.txt that these user agents are not blocked. Then run a Screaming Frog crawl with the AI crawler's user agent.
Check your CDN and web application firewall too, so you are not blocking these crawlers by accident. Look closely at Cloudflare. It is one of the most popular CDNs, and it has its own AI crawler settings.
On one audit, for a pharma marketplace, the CDN allowed one OpenAI crawler and blocked the other. It was a critical finding. If you block AI crawlers, you are choosing to keep your site out of the training data. In my view that is lethal for visibility: the brand loses citations and recommendations.
| Company | Bot | What it is for, per the company's own documentation |
|---|---|---|
| OpenAI | GPTBot | Content that may be used to train its models |
| OpenAI | OAI-SearchBot | Surfacing websites in ChatGPT's search features |
| OpenAI | ChatGPT-User | Fetching a page when a user's action calls for it |
| Anthropic | ClaudeBot | Content that could be used to train its models |
| Anthropic | Claude-SearchBot, Claude-User | Search results for Claude users, and fetching a page for a user's question |
| Perplexity | PerplexityBot, Perplexity-User | Surfacing and linking websites in its search results, and fetching a page for a user's question |
| Google-Extended | A robots.txt token, not a crawler. It covers Gemini training and grounding. It does not control AI Overviews or AI Mode |
What the documentation says. OpenAI says the GPTBot and OAI-SearchBot settings are independent, so blocking the training crawler does not by itself remove a site from ChatGPT search. What staying out of training data costs you in citations is my view from audits, and no AI company documents it. Check every bot on its own line. Cloudflare changed its AI crawler defaults in September 2026, and says 17% of sites on its network block AI training.
AI Overviews and AI Mode: there is no single tool
No single tool gives you this data. I combine several tools with my own AI workflows.
- Search Console. Its generative AI report, launched in June 2026, is my first check on any site with Search Console access. It shows how many pages appear on AI Overviews and Google's other AI features.
- My own extension. The report shows impressions only, so I built an extension that places the property's Search clicks and CTR beside it.
- A regex for AI Mode. Google has no separate view for AI Mode. I filter Search Console queries with a regex of conversational words, which surfaces many queries where the brand is visible.
- Semrush and Ahrefs. Apply the AI Overviews filter to compare organic keywords with the keywords where the brand ranks on AI Overviews.
- A custom workflow on the DataForSEO API. It tracks my must-have keywords: how often the brand appears on those AI Overviews, and how often it is linked.
For ChatGPT, Gemini and Perplexity, I use Ahrefs Brand Radar and Semrush's AI toolkit, plus prompt tracking tools such as Peec AI, Profound and AirOps. They track a sample of prompts: how the brand appears, and which other brands are mentioned.
What the documentation says. The Generative AI performance report has one metric, impressions, and covers AI Overviews and AI Mode together. AI Mode clicks and impressions have counted in the standard Performance report since June 2025, so the regex finds queries that look like AI Mode prompts. It cannot prove where a query came from.
llms.txt: a hygiene item, not a visibility lever
I advise keeping llms.txt as a hygiene item, but it is not a strong recommendation. I have seen no impact on AI search visibility, and no growth in citations or mentions, for any brand using it. Keeping the file does no harm if it costs little. It is not a mandate from my side, and I do not include it in my audits.
If you are making llms.txt your P0 implementation to increase AI search visibility, that's a PR scam, because it doesn't work.
What the documentation says. As of October 2026, Google's own guide says Search and its generative AI features do not use llms.txt files. OpenAI, Anthropic and Perplexity do not mention the file in their crawler documentation. Ahrefs checked 137,210 sites: 97% of the llms.txt files it found were not requested by anything in a month.
From findings to shipped fixes
Prioritisation: lowest effort, highest impact first
My framework weighs effort against impact and priority. I always start with the lowest-effort, highest-impact item. A high-effort, high-impact item must be tied to a revenue metric. That is how product, engineering and business teams work, and how alignment happens.
I always build a table with the impact in leads and revenue, the effort, the time to execute and the team's bandwidth. Forecasting is not a detailed part of the audit. You cannot promise an exact traffic number, but you should always project one. Whether the projection is 80%, 60% or even 50% accurate matters less than having it.
Getting product and engineering to prioritise it
Show what the brand is missing. Product heads, CTOs and business leaders decide only when they see the value. So tie each item to the total addressable market, the search volume and the demand the brand is losing.
Share the credit too. The appreciation should go to the product and technology teams, not only to the organic team. When a fix moves everyone's KPI, it gets prioritised.
Handing over to developers
Every audit needs an executable instruction slide: exactly what to execute, with the effort, impact and priority of each item. Then:
- Do not start by writing PRDs or technical requirement documents.
- Walk the point of contact through the audit and every task, whether that is the SEO head, the marketing head or the product head.
- Get the items into the current sprint plan or roadmap.
- Then write a detailed PRD or TRD for each item: what it is, and how to execute it.
Getting fixes into the pipeline is the SEO's job, because ownership of organic growth sits with them. Product and engineering execute. If growth metrics are not in their KRAs and KPIs, SEO fixes may not get considered.
How much actually gets implemented
I have seen brands implement everything within a couple of months and grow well. I have also seen brands take four to six months to change the metadata on one page. In larger organisations, a fix that is not on the product or engineering roadmap does not get implemented.
| Kind of company | Recommendations implemented per quarter, in my experience |
|---|---|
| Hyperscale, fast-moving startups where organic growth is important | 80 to 90% |
| Smaller businesses | 50 to 60% |
| Large, monolithic enterprises | 10 to 30% |
No matter how many good slides we create, how many impactful business documents we create, if nothing gets implemented, no results are going to come.
After the audit: monitoring, not another audit
Once the fixes have made the site stable, you do not need another full audit. You need monitoring systems that watch the pages and alert you when something breaks in production, or when a team ships something new.
| How often | What I check |
|---|---|
| Daily | Monitoring alerts on page changes |
| Weekly | Search Console, to see whether Google has flagged anything. Server logs and crawl health |
| Monthly to quarterly | Content audits: content decay and content pruning |
| As needed | Pages that fall under query deserves freshness (QDF) need regular updates |
Before a release, everything is vetted on staging as a quality gate. I also built my own AI-powered tool, Nighthawk. It tracks every page at a set frequency across 28 to 30 on-page parameters, including metadata, schema, content and meta robots tags. A bad release from any department can hurt SEO, so every substantial change is flagged to us.
The tool stack for an enterprise audit
Screaming Frog, Ahrefs, Semrush and Claude, plus a few rendering extensions, are more than sufficient for a technical SEO audit.
| Tool | What I use it for |
|---|---|
| Screaming Frog | My main tool for auditing a site in depth: extracting content with regex, auditing with the OpenAI or Claude APIs, connecting Google Analytics to find orphan pages, and checking how content is rendered |
| Ahrefs and Semrush | Existing data: architecture, keywords, past traffic trends, backlinks, and how the site behaved in recent updates |
| Search Console and its API | The main data source, when the client shares access |
| Claude or ChatGPT | Content auditing, and analysis on top of the crawl data |
| My own tools | Nighthawk for page changes, Content Apex for content decay and pruning, a server log analyser, and SSR Inspector for rendering |
I think the ultra-expensive enterprise platforms are now overrated. Much of what they do can be handled with custom workflows, a data warehouse and a layer of AI. Screaming Frog plus the Search Console API is more than enough to carry out an audit, with Semrush and Ahrefs as the top layer for data.
Where AI fits, and where a human should be involved
Do not make AI do what it is not good at. Ask an AI to crawl a 50,000-page website and it will not. Use a Screaming Frog MCP to crawl 60,000 pages, then ask the AI for recommendations based on that crawl, and it will do the job well.
If AI is not fed from the right sources, it may hallucinate, and you may act on wrong data. Set a clear guardrail: if the data is not in this source, do not evaluate it and do not believe it. I have measured this on content audits, in my benchmark of six OpenAI models on 100 pages.
How long an enterprise SEO audit takes, and what it costs
My basic audit starts from $1,000. The range is $1,000 to $5,000, depending on the size of the website, the brand, the business and the number of geographies. This is what I charge as of now.
| Site | What I charge | How long it takes |
|---|---|---|
| Local SEO website, around 100 pages | Around $600 to $800 | A week or two |
| Small or medium business | From $1,000 | A week or two |
| Enterprise, around 10,000 pages | From $1,000, the bare minimum | 4 weeks with AI |
| Large enterprise, more than 100,000 or 200,000 pages | Up to $5,000 | 4 to 6 weeks |
Market rates are high. As an Indian consultant, my pricing works for many businesses, and the audit covers more than technical and content checks. I also assess the site against Google's search quality rater guidelines and spam policies. You can see the kind of results in my MPL case study, and how I work on my enterprise SEO consultant page.
Enterprise SEO audit FAQ
What is an enterprise SEO audit?
A review of how a large website is crawled, rendered, indexed and ranked, and how it appears on AI search. It should give the conclusion of every finding, with the effort, impact and priority of each item. A crawl report alone is not an audit.
How long does an enterprise SEO audit take?
Four to six weeks from scratch. Four weeks is my fastest time with AI. A smaller business can be audited in a week or two.
How much does an enterprise SEO audit cost?
I charge $1,000 to $5,000, depending on the size of the website, the brand, the business and the number of geographies.
Can ChatGPT do an SEO audit?
Not on its own. Ask an AI to crawl a 50,000-page website and it will not. Get the data from a crawler through an MCP, ask the AI for recommendations on that data, and review the output yourself.
How often should an enterprise site be audited?
Once the site is stable, you do not repeat the full audit. Monitoring alerts run daily, Search Console and server logs are checked weekly, and content audits happen monthly to quarterly.
Which tools do I need for an enterprise SEO audit?
Screaming Frog plus the Search Console API is enough to carry out an audit, with Semrush and Ahrefs as the top layer for data.